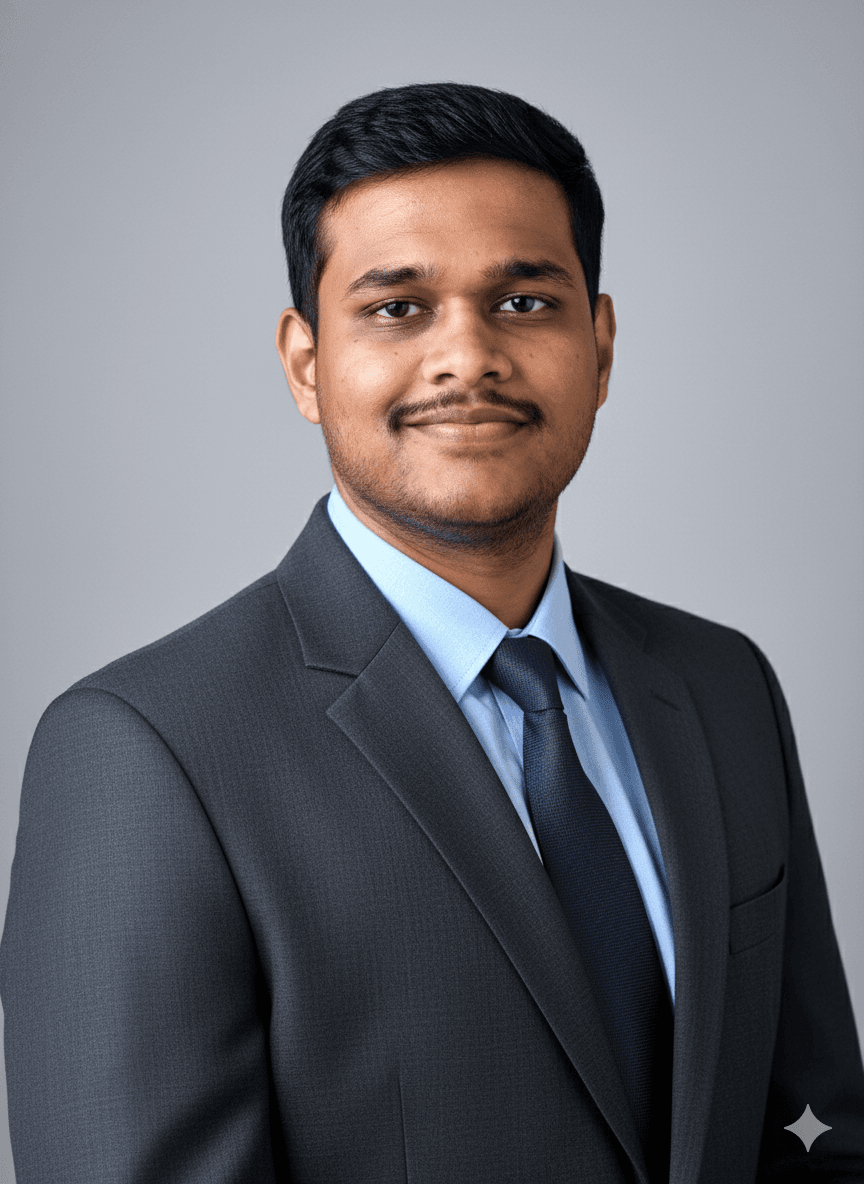
AI/ML Engineer & Data Scientist

Building production AI and responsible ML: autonomous agents, RAG pipelines, and fair, governed models that ship.

Tysons, VA

A data scientist's rigor,
an engineer's ship-it instinct.

Adarsh Gorremuchu, AI/ML Engineer & Data Scientist

I'm an AI/ML Engineer and Data Scientist who ships production-grade AI while keeping it fair, governed, and observable. I architect autonomous agent workflows and RAG systems with vector databases, and I bring a data-scientist's rigor (statistical modeling, hypothesis testing, disparate-impact analysis, and responsible-AI governance) to every model I put into production. My work spans the full stack, from PySpark pipelines on Azure Databricks and feature engineering to translating results into clear Power BI narratives for technical and non-technical stakeholders alike.

Jan 2023 - Dec 2024
George Mason University
M.S. Data Analytics Engineering
Machine Learning, Data Engineering, Cloud Computing, Statistics
Get my resume
4+
Years across ML, analytics & data engineering
70-85%
Manual effort cut via AI agents
40%
RAG retrieval relevance gain
35%
Faster analysis via ML pipelines

What I work with

AI / ML

LLMsRAGLangChainSemantic KernelPyTorchTensorFlowNLPPrompt EngineeringMulti-Agent Systems

Data Science & Statistics

Predictive ModelingRegressionClusteringClassificationHypothesis TestingEDAFeature EngineeringModel Lifecycle

Responsible AI & Compliance

Disparate Impact AnalysisBias AssessmentResponsible AIModel GovernanceFair Lending Frameworks

Data Engineering & Cloud

Azure DatabricksPySparkSparkSQLAirflowSnowflakeBigQueryRedshiftAWS LambdaDockerTerraform

Languages

PythonSQLPySparkRSAS/StatBash

Visualization & BI

Power BITableauData StorytellingDAXDashboards

Where I've shipped.

AI/ML Engineer & Data Scientist

Ampcus Inc·Chantilly, VA
Jun 2025 - Present

Building autonomous agent workflows and production RAG systems, with responsible-AI governance and statistical rigor across the model lifecycle.

  • Architected autonomous agent workflows using LLMs, tool-use, and decision logic, cutting manual effort by 70-85% across internal operations.
  • Engineered production RAG systems with embeddings and vector databases (OpenSearch, Pinecone), boosting retrieval relevance by 40%.
  • Applied disparate-impact analysis and statistical bias assessment to review model outputs for fairness risk; partnered with compliance and legal on risk-mitigation decisions.
  • Designed and validated predictive ML models end-to-end: feature engineering, hypothesis testing, and lifecycle documentation aligned with responsible-AI governance.
  • Ran descriptive, predictive, and prescriptive analyses on large datasets with Python and PySpark on Azure Databricks; built Power BI dashboards to communicate results to technical and non-technical leadership.
  • Deployed serverless components on AWS Lambda, SQS, and Step Functions; packaged with Docker; provisioned via Terraform.
LLMsRAGPySparkAzure DatabricksResponsible AIPower BIAWS LambdaTerraform

Cloud Data Engineer & ML Developer

Community Informatics Lab (GMU)·Fairfax, VA
May 2024 - Nov 2024

Built LLM-assisted analytics and multi-cloud data architecture supporting 20+ research projects.

  • Developed LLM-assisted analytics for summarization, classification, and context extraction using RAG and prompt strategies, shortening analysis turnaround by 35%.
  • Designed multi-cloud architecture with Snowflake, BigQuery, and NoSQL supporting 20+ projects with standardized schemas.
  • Trained and evaluated ML pipelines with TensorFlow, PyTorch, clustering, and statistical methods, elevating forecasting quality by 35%.
  • Streamlined orchestration using Airflow, Spark, and Databricks, accelerating pipeline runtimes by 55% while sustaining 99.9% reliability.
PythonTensorFlowPyTorchSnowflakeBigQueryAirflowSparkDatabricks

Data Engineer & BI Developer

TriSX Global India Pvt Ltd·Hyderabad, India
Dec 2020 - Dec 2022

Designed ETL pipelines, predictive models, and executive BI dashboards for enterprise reporting.

  • Designed ETL pipelines and analytics data models using Databricks, Spark, and warehouses (Redshift, Snowflake, BigQuery), decreasing reporting latency by 55%.
  • Applied predictive modeling and KPI forecasting using Python and TensorFlow, increasing planning accuracy by 20%.
  • Produced executive dashboards in Power BI and standardized KPI definitions, increasing stakeholder adoption by 30%.
DatabricksSparkRedshiftSnowflakePower BIPythonTensorFlow

Things I've built.

Featured Project

Bias & Fairness Assessment: AI Model Governance

Built a fairness-review pipeline that evaluates AI/ML model inputs, assumptions, and outcomes for potential disparate impact. Applied statistical bias-assessment techniques on Azure Databricks with PySpark, documented findings in technical reports, and collaborated with compliance stakeholders to support risk-mitigation and corrective-action planning.

  • Statistical bias assessment against responsible-AI governance frameworks
  • Disparate-impact analysis on model outputs and business policies
  • Documented reviews supporting compliance risk-mitigation decisions
PythonPySparkAzure DatabricksDisparate Impact AnalysisResponsible AI
Featured Project

Serverless RAG Architecture & Vector Search

Designed a production RAG architecture using OpenSearch and Pinecone to index enterprise knowledge. Containerized services with Docker for consistent deployment, provisioned infrastructure via Terraform, and optimized vector queries to hit sub-second latency for semantic retrieval.

  • Sub-second vector search latency in production
  • IaC-provisioned via Terraform across environments
  • Containerized with Docker for portable deployment
OpenSearchPineconeDockerTerraformAzure AIPython
Featured Project

Campaign Outcome Prediction & Ranking Model

Engineered a predictive ranking model analyzing campaign and unit data from PMX and DOA systems. Optimized feature selection to forecast performance outcomes and deployed on AWS infrastructure with results piped into Power BI dashboards for 10+ stakeholders.

  • Deployed on AWS with end-to-end pipeline integration
  • Powered decision-making for cross-functional team of 10+
  • Feature engineering optimized for forecast accuracy
PythonAWSPower BIPMXDOAMachine Learning
Featured Project

EPCIS Supply Chain Inbound Tracking

Built an EPCIS-compliant inbound tracking module enabling organization admins to manage supplier transactions. Implemented 'Add Order' capabilities, real-time shipment visibility, and standardized supplier inbound events to comply with global traceability standards, reducing manual tracking errors by 40%.

  • 40% reduction in manual tracking errors
  • Compliant with global EPCIS traceability standards
  • Real-time shipment visibility for admins
EPCISCloud ArchitectureREST APIsBackend Development

Let's talk.

Open to AI/ML Engineer, Data Scientist, and ML Platform roles. Reach out about opportunities, collaborations, or responsible-AI work.